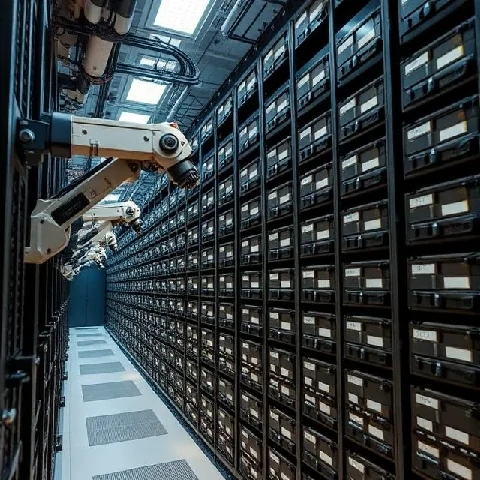
Data archiving moves inactive data to long-term storage. The data is not deleted. It is set aside. The active systems run faster because they carry less weight. Compliance departments keep archives for regulatory requirements. Legal teams keep them for litigation holds. Researchers keep them for historical reference. The archive is a warehouse, not a landfill.
The distinction between archiving and backup matters. A backup is a copy for recovery. An archive is the primary copy of data that is no longer in active use. Both need to be secure. Both need to be findable. Archives often use cheaper, slower storage: tape, optical media, or cold cloud tiers. Retrieval takes time, sometimes hours. That is acceptable for data that nobody has touched in years. The challenge is knowing what is in the archive. Metadata, indexing, and retention schedules keep the archive usable. An archive without an index is a black hole. You know the data is in there. You just cannot find it. Retention policies define how long each category of data stays. After the retention period, the data is deleted. Keeping everything forever is expensive and risky. The archive should shrink as well as grow.
Archiving considerations
- Retention schedule — how long each data type is kept
- Storage medium — tape, optical, or cold cloud
- Indexing — metadata that makes archived data findable
- Retrieval time — acceptable delay for access
- Disposal — secure deletion when retention ends
An archive is a promise. The data will be there when you need it. Keeping that promise requires planning.
Comments
No comments yet. Be the first to share a thought.
Leave a comment