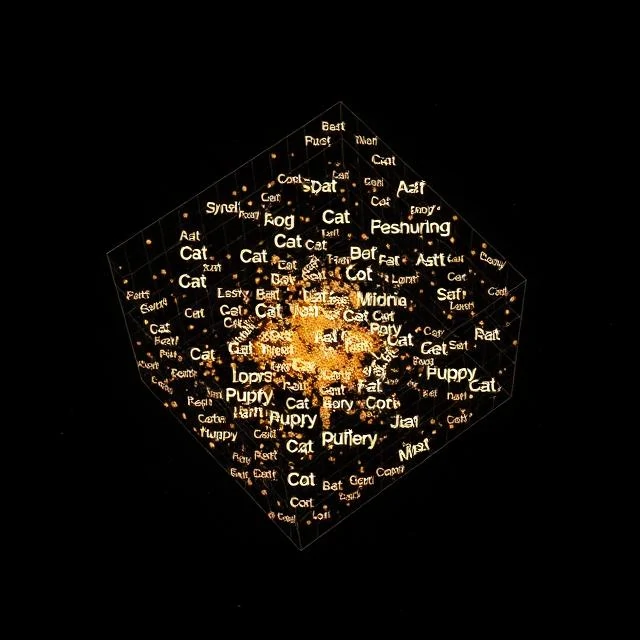
In a good word embedding, "king" minus "man" plus "woman" lands near "queen." That arithmetic works because the vectors encode meaning, not just spelling. Each word becomes a dense list of numbers, typically 100 to 300 dimensions, positioned so that similar words sit close together in vector space.
Older representations treated words as isolated symbols. A one-hot vector for "cat" said nothing about "kitten." Embeddings changed that by training on large text corpora: words that appear in similar contexts end up with similar vectors. The distributional hypothesis, roughly "you shall know a word by the company it keeps," is the engine behind the whole idea.
Popular methods
- Word2Vec, which predicts a word from its neighbors or vice versa
- GloVe, which factors a global co-occurrence matrix
- FastText, which represents words as bags of character n-grams
- Contextual embeddings from BERT and similar models, where a word's vector depends on its sentence
Static embeddings like Word2Vec assign one vector per word, so "bank" has the same representation in "river bank" and "bank account." Contextual models fix that ambiguity, which is why they now dominate. The trade-off is cost: computing a contextual vector requires running the whole model.
Comments
No comments yet. Be the first to share a thought.
Leave a comment