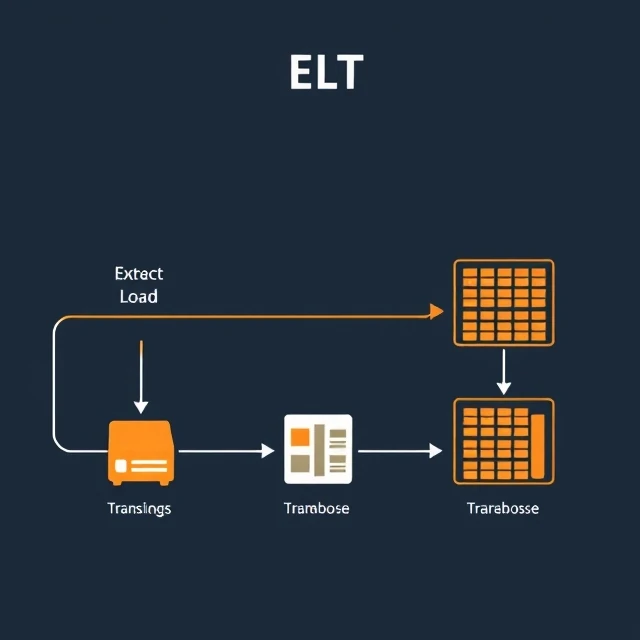
ELT stands for extract, load, transform. It reverses the traditional ETL order. Data is extracted from sources and loaded directly into the target system in its raw form. Transformations happen inside the target, usually a cloud data warehouse, using its compute power. The approach became popular as cloud warehouses scaled and their processing costs dropped. Why transform on a separate server when the warehouse can do it faster and cheaper?
ELT has advantages. Raw data is preserved in the warehouse, so transformations can be re-run without re-extracting from sources. New transformations can be applied retroactively. The target system handles the heavy lifting, which simplifies the pipeline architecture. Tools like dbt brought software engineering practices to transformation: version control, testing, documentation, and modular code. The trade-off is that the warehouse must be powerful enough to handle both storage and transformation. It also means raw, potentially sensitive data sits in the warehouse before transformation. Access controls must protect it. ELT is not universally better than ETL. For some workloads, transforming before loading reduces the volume of data that reaches the warehouse. For others, the flexibility of ELT wins. The choice depends on the target system's capabilities and the team's preferences.
ELT characteristics
- Load raw — data lands in the warehouse untouched
- Transform in place — warehouse compute handles transformations
- Reprocessable — transformations can be re-run on raw data
- Simpler pipelines — fewer moving parts
- Warehouse-dependent — requires scalable compute
ELT is ETL turned inside out. The warehouse does the work. The pipeline just moves data.
Comments
No comments yet. Be the first to share a thought.
Leave a comment