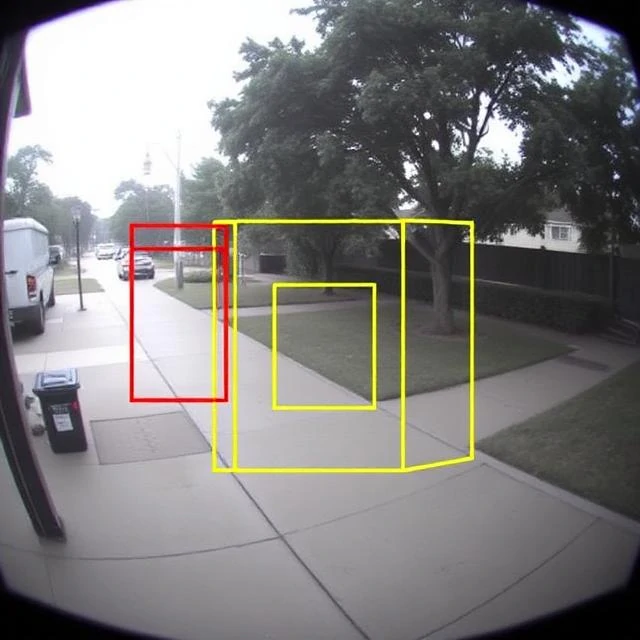
Computer vision gives robots the ability to interpret visual information. Cameras capture images. Algorithms extract meaning: edges, shapes, objects, faces, motion. The robot uses that meaning to navigate, pick, inspect, or track.
Early computer vision relied on hand-coded rules. Find edges, match templates, measure distances. It worked in controlled lighting and failed everywhere else. Deep learning changed that. Convolutional neural networks learn features from labeled images. They can recognize a cat, a crack in a weld, or a ripe strawberry without being told what to look for.
What computer vision enables
- Object detection and classification.
- Pose estimation for grasping.
- Visual servoing for precise alignment.
- Defect detection in manufacturing.
- Simultaneous localization and mapping (SLAM).
Vision is hard because the world is messy. Lighting changes. Objects overlap. Reflections confuse cameras. A robot that sees well in the lab may fail on the factory floor. Engineers use multiple cameras, structured light, and depth sensors to add robustness. They also train on data from the real environment, not just clean datasets. Computer vision is the most active research area in robotics for a reason. If a robot can see, it can do almost anything. If it cannot, it is limited to blind, repetitive motion.
Comments
No comments yet. Be the first to share a thought.
Leave a comment